Take action
$2,000
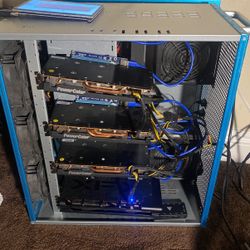
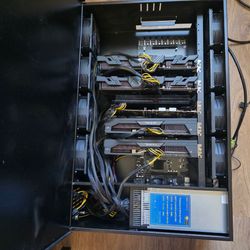
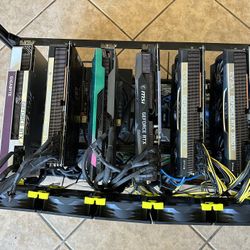
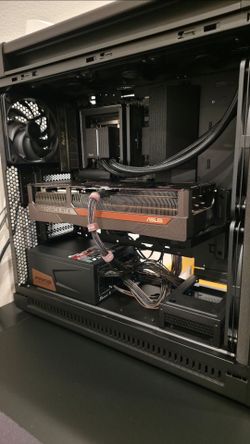
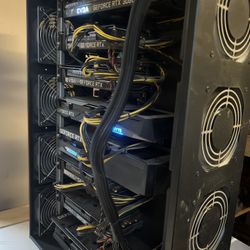
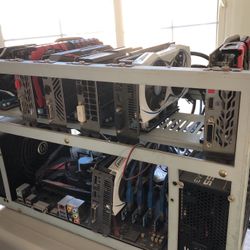
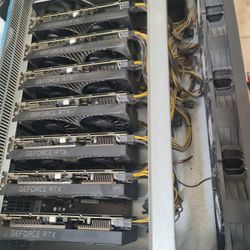
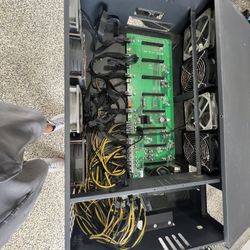
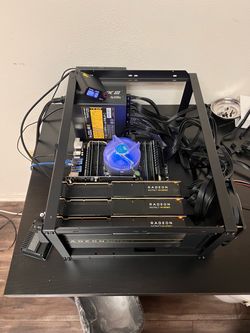
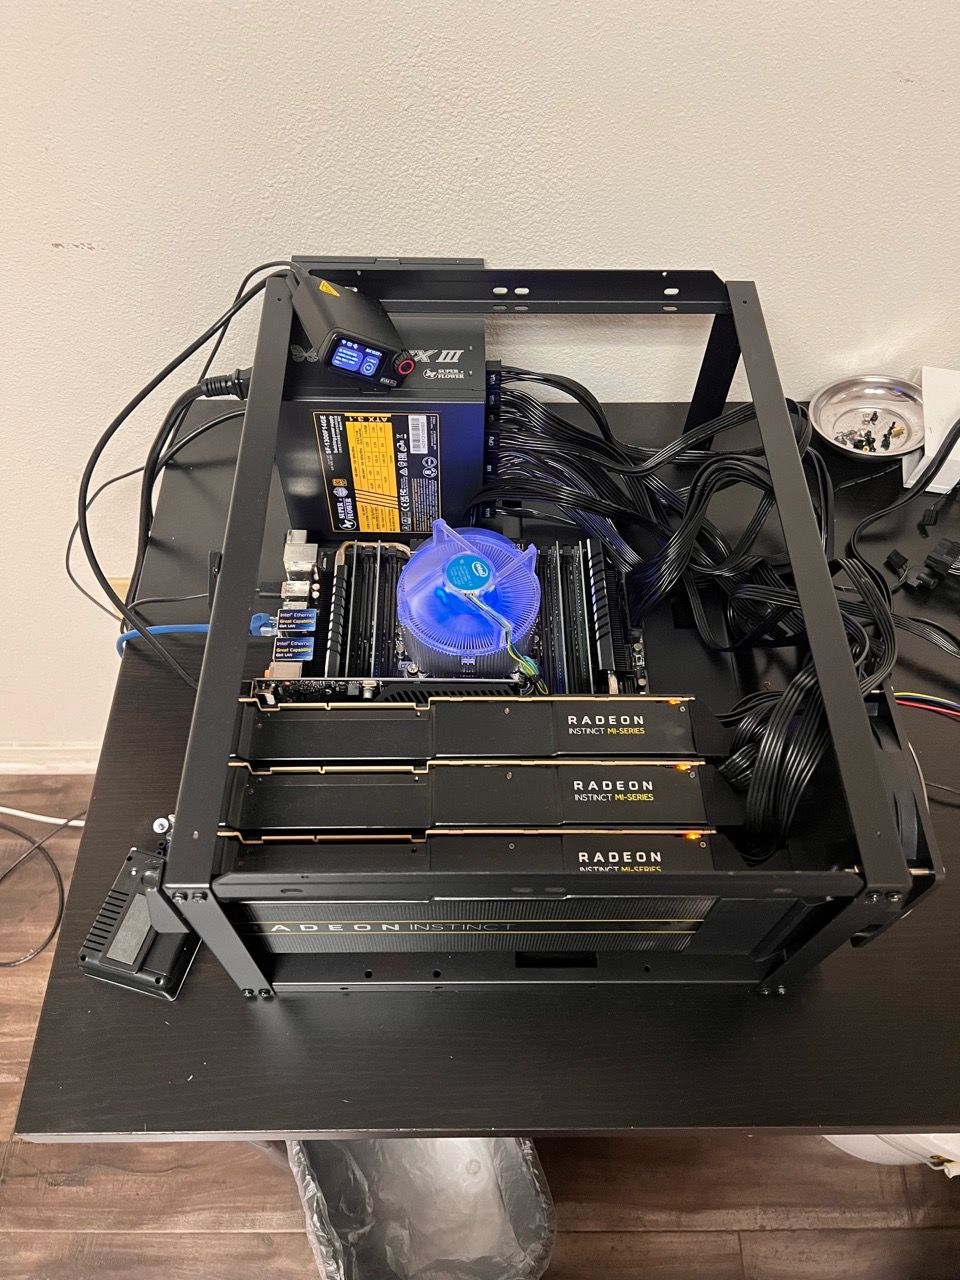
AI server. 3x MI50 32gb, 96gb total
Last updated 2 days ago in Santa Ana, CA
Listed in categories:

Chat securely on the app

Description
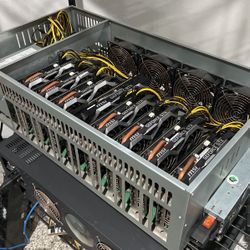
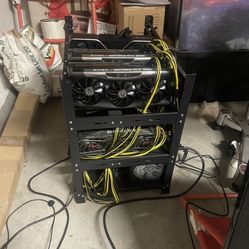
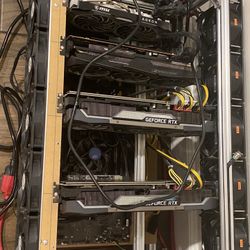
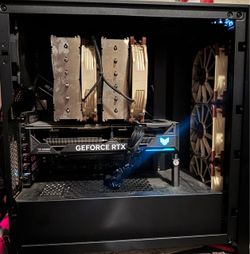
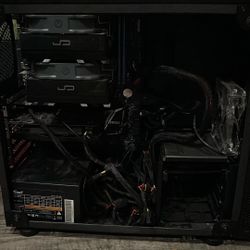
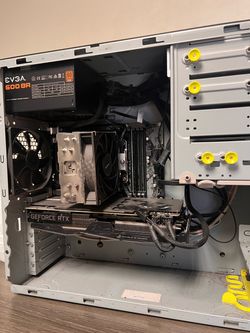
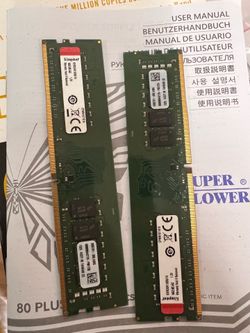
96GB VRAM AI server for running large language models locally. Fully set up and working - powers on straight into a web chat interface with three models loaded and ready. SPECS GPUs: 1x EVGA GT 1030 2gb (for display), 3x AMD Vega 20 32GB = 96GB HBM2 total (2x Radeon Pro Vega II, 1x Instinct MI50 - same gfx906 chip, all three running at full x16) CPU: Intel i7-6900K, 8 core / 16 thread, 3.2GHz Motherboard: ASUS X99-E WS, true triple x16 via PLX switch RAM: 32GB DDR4-2400 (4x8GB, 4 slots open, takes up to 128GB) Storage: 2TB Sabrent Rocket Q NVMe PSU: 1x Superflower 1300w, 1x Superflower 800w Cooling: 40mm fan on each card, holds 48-54C under sustained full load SPEEDS I MEASURED ON THIS MACHINE GPT-OSS 20B - 106 tokens/sec Qwen3 30B - 74 tokens/sec Gemma 4 26B - 70 tokens/sec Qwen3.6 35B - 67 tokens/sec Qwen3.8 27B - 22 tokens/sec Running Ubuntu 24.04 with ROCm and llama.cpp already built and configured for these cards, plus Open WebUI web interface. I'll include my full setup documentation - saves you a lot of trial and error.
Details
Condition
Used (normal wear)
Item location map
Map is approximate to keep seller’s location private.